What Is a Linked List in Embedded Systems?
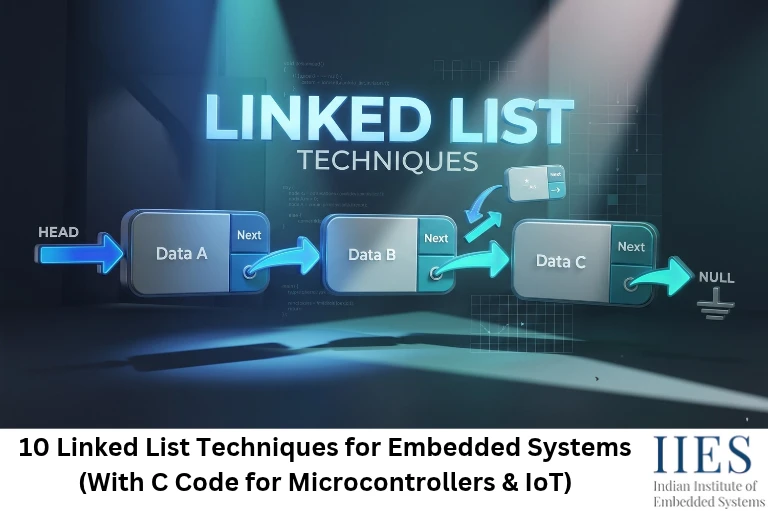
A linked list is a collection of nodes in which each node stores data and one or more pointers connecting it to another node.
A basic singly linked list contains two components:
The first node is called the head. The last node points to NULL, indicating that there are no more nodes.
Basic Linked List Structure in C
The following example defines a node that stores a sensor reading:
#include

typedef struct Node {
    int16_t sensor_value;
    struct Node *next;
} Node;
Here, sensor_value stores a sensor measurement, while next points to the next node.
For example, an IoT device might use a linked list to store a sequence of temperature readings before transmitting them to a gateway.
Example structure:
Head -> [25] -> [27] -> [26] -> NULL
Each node contains a temperature reading and a pointer to the next node.
Linked lists can be useful when firmware needs to manage collections of objects that change during execution.
Common applications include:
Sensor data management: Store readings collected at different times.
Communication buffers: Track packets waiting for processing or transmission.
Task scheduling: Maintain a list of pending tasks in a simple scheduler.
Memory management: Track free memory blocks in a custom allocator.
Device drivers: Organize registered devices, callbacks, or resources.
IoT applications: Manage incoming messages and queued sensor events.
However, linked lists are not always the best choice. They require extra memory for pointers, involve pointer dereferencing, and may have unpredictable execution times when traversing long lists. For small microcontrollers, a fixed-size array or ring buffer may be more appropriate when memory usage and timing must remain predictable.
10 Linked List Techniques for Embedded Systems
The following techniques cover essential linked list operations, pointer manipulation, and practical approaches for embedded firmware development.
1. Linked List Traversal
Traversal is the process of visiting each node in a linked list, starting from the head and continuing until the end of the list.
It is commonly used when firmware needs to inspect stored sensor values, process queued events, or transmit collected data.
How Traversal Works
Start with the head pointer.
Read the data stored in the current node.
Move to the next node using the next pointer.
Continue until the pointer becomes NULL.
C Code Example
#include

typedef struct Node {
    int data;
    struct Node *next;
} Node;

void traverse_list(const Node *head)
{
    const Node *current = head;

    while (current != NULL) {
        printf("%d ", current->data);
        current = current->next;
    }

    printf("\n");
}
Embedded Systems Application
Consider an environmental monitoring device that stores several sensor readings in a linked list. Traversal allows the firmware to process each reading before sending the collected data to an IoT gateway.
Time complexity: O(n), where n is the number of nodes.
Important consideration: Traversal takes longer as the list grows. Avoid traversing large lists inside high-priority interrupt service routines (ISRs).
2. Inserting a Node at the Beginning
Insertion at the beginning adds a new node before the current head. It is one of the simplest linked list techniques because it does not require traversing the list.
How It Works
Create or obtain a new node.
Set its next pointer to the current head.
Update the head pointer to the new node.
C Code Example
#include

typedef struct Node {
    int data;
    struct Node *next;
} Node;

Node *insert_front(Node *head, int value)
{
    Node *new_node = malloc(sizeof(Node));

    if (new_node == NULL) {
        return head;
    }

    new_node->data = value;
    new_node->next = head;

    return new_node;
}
Embedded Systems Application
A firmware module can use front insertion to add the latest event to the beginning of an event list. This can be useful when recent events need to be accessed first.
Time complexity: O(1).
Important consideration: This example uses malloc(). On a memory-constrained microcontroller, consider a fixed-size node pool or statically allocated storage to avoid heap fragmentation and allocation failures.
3. Inserting a Node at the End
Insertion at the end adds a node after the current last node. This technique is useful when maintaining data in the order in which it arrives.
How It Works
Create a new node.
Set its next pointer to NULL.
If the list is empty, make the new node the head.
Otherwise, traverse the list to find the last node.
Connect the last node to the new node.
C Code Example
#include

typedef struct Node {
    int data;
    struct Node *next;
} Node;

Node *insert_end(Node *head, int value)
{
    Node *new_node = malloc(sizeof(Node));

    if (new_node == NULL) {
        return head;
    }

    new_node->data = value;
    new_node->next = NULL;

    if (head == NULL) {
        return new_node;
    }

    Node *current = head;

    while (current->next != NULL) {
        current = current->next;
    }

    current->next = new_node;

    return head;
}
Embedded Systems Application
An IoT device can append sensor measurements to a list in the order they are collected. This makes it easier to process or transmit readings in sequence.
Time complexity: O(n) when only the head pointer is available.
Maintaining a separate tail pointer allows insertion at the end in O(1) time, provided the tail pointer is kept up to date.
Important consideration: For frequent data collection, a fixed-size ring buffer may offer more predictable performance and lower memory overhead.
4. Deleting a Node by Value
Deletion removes a node from a linked list. It requires updating the pointer that connects the previous node to the node after the one being removed.
The operation must handle three cases:
C Code Example
#include

typedef struct Node {
    int data;
    struct Node *next;
} Node;

Node *delete_value(Node *head, int value)
{
    Node *current = head;
    Node *previous = NULL;

    while (current != NULL && current->data != value) {
        previous = current;
        current = current->next;
    }

    if (current == NULL) {
        return head;
    }

    if (previous == NULL) {
        head = current->next;
    } else {
        previous->next = current->next;
    }

    free(current);

    return head;
}
Embedded Systems Application
A firmware application may remove a completed event or discard an obsolete entry from a queue of pending operations.
Time complexity: O(n), because the node may need to be located before deletion.
Important consideration: Only call free() on memory obtained from a compatible dynamic allocation function. If the nodes belong to a static array or custom memory pool, return them to that allocator instead.
5. Searching for a Node
Searching identifies whether a node contains a particular value. It is useful when firmware needs to locate a specific sensor record, device identifier, or event.
C Code Example
typedef struct Node {
    int data;
    struct Node *next;
} Node;

Node *search_list(Node *head, int target)
{
    Node *current = head;

    while (current != NULL) {
        if (current->data == target) {
            return current;
        }

        current = current->next;
    }

    return NULL;
}
Embedded Systems Application
A device management module may search a linked list for a particular device ID before updating its configuration.
Time complexity:
Best case: O(1), when the first node matches.
Worst case: O(n), when the target is at the end or is absent.
Important consideration: A linked list does not support direct indexing like an array. If firmware repeatedly searches large collections by ID, a hash table or another suitable data structure may be more efficient.
6. Reversing a Linked List
Reversing a linked list changes the direction of its links so that the last node becomes the new head.
This operation is useful when firmware needs to process a sequence in reverse order without allocating a second list.
How It Works
Three pointers are used:
previous: The node that has already been processed.
current: The node being processed.
next: The next node to visit.
At each step, the current node’s pointer is reversed, and the algorithm advances to the next node.
C Code Example
typedef struct Node {
    int data;
    struct Node *next;
} Node;

Node *reverse_list(Node *head)
{
    Node *previous = NULL;
    Node *current = head;

    while (current != NULL) {
        Node *next = current->next;

        current->next = previous;
        previous = current;
        current = next;
    }

    return previous;
}
Embedded Systems Application
Reversal can help reorganize stored event records or process a linked sequence in the opposite direction.
Time complexity: O(n).
Auxiliary space: O(1), because the algorithm uses a fixed number of pointers.
Important consideration: Always update the head pointer with the returned value. Otherwise, the application may continue referencing the old head, which is now the last node.
7. Finding the Middle Node Using Two Pointers
The slow and fast pointer technique finds the middle node without first counting every node.
The slow pointer advances one node at a time, while the fast pointer advances two nodes at a time. When the fast pointer reaches the end, the slow pointer is at the middle.
C Code Example
typedef struct Node {
    int data;
    struct Node *next;
} Node;

Node *find_middle(Node *head)
{
    Node *slow = head;
    Node *fast = head;

    while (fast != NULL && fast->next != NULL) {
        slow = slow->next;
        fast = fast->next->next;
    }

    return slow;
}
Embedded Systems Application
This technique can help divide a linked collection into two sections for subsequent processing. It can also be useful in educational firmware projects that demonstrate pointer-based algorithms.
For an even number of nodes, this implementation returns the second of the two middle nodes.
Time complexity: O(n).
Auxiliary space: O(1).
Important consideration: This technique assumes a valid, acyclic linked list. If the list contains a cycle, the loop may not terminate.
8. Detecting a Cycle in a Linked List
A cycle occurs when a node points back to an earlier node instead of eventually reaching NULL.
Unintended cycles can cause infinite loops during traversal. Floyd’s cycle detection algorithm uses slow and fast pointers to identify them without storing a separate collection of visited nodes.
C Code Example
#include

typedef struct Node {
    int data;
    struct Node *next;
} Node;

bool has_cycle(Node *head)
{
    Node *slow = head;
    Node *fast = head;

    while (fast != NULL && fast->next != NULL) {
        slow = slow->next;
        fast = fast->next->next;

        if (slow == fast) {
            return true;
        }
    }

    return false;
}
Embedded Systems Application
Cycle detection can help diagnose corrupted linked-list structures during firmware testing. It is particularly useful when debugging pointer manipulation or custom memory management code.
Time complexity: O(n).
Auxiliary space: O(1).
Important consideration: Cycle detection is a debugging and validation technique, not a substitute for correct pointer handling. Firmware should still validate ownership, initialization, and memory lifetime.
9. Implementing a Circular Linked List
In a circular linked list, the last node points back to the first node instead of pointing to NULL.
This structure allows firmware to cycle through a collection of nodes repeatedly without returning to the head through a separate reset operation.
Circular Linked List Structure
For a circular singly linked list:
Head -> [A] -> [B] -> [C] -> Head
There is no NULL pointer at the end of the cycle.
C Code Example
typedef struct Node {
    int data;
    struct Node *next;
} Node;

void traverse_circular(const Node *head)
{
    if (head == NULL) {
        return;
    }

    const Node *current = head;

    do {
        /* Process current->data here. */
        current = current->next;
    } while (current != head);
}
Embedded Systems Application
Circular linked lists can support round-robin processing, where firmware visits a sequence of tasks or devices repeatedly.
However, a circular linked list is not the same as a ring buffer. A ring buffer normally stores elements in a fixed-size array and wraps its read and write indices around the array boundaries.
Important consideration: The traversal condition must match the circular structure. Using while (current != NULL) would not terminate for a correctly formed circular list.
10. Managing Nodes with a Fixed-Size Memory Pool
Dynamic memory allocation can be challenging on microcontrollers because repeated allocation and deallocation may fragment the heap. A fixed-size node pool provides an alternative by allocating storage for nodes in advance.
Instead of calling malloc() for every insertion, the firmware obtains an unused node from a predefined array. When a node is no longer needed, it returns that node to the pool.
C Code Example
#include

#define NODE_POOL_SIZE 16

typedef struct Node {
    int data;
    struct Node *next;
} Node;

static Node node_pool[NODE_POOL_SIZE];
static Node *free_list = NULL;

void node_pool_init(void)
{
    free_list = NULL;

    for (size_t i = 0; i < NODE_POOL_SIZE; i++) { node_pool[i].next = free_list; free_list = &node_pool[i]; } } Node *allocate_node(int value) { if (free_list == NULL) { return NULL; } Node *node = free_list; free_list = free_list->next;

    node->data = value;
    node->next = NULL;

    return node;
}

void release_node(Node *node)
{
    if (node == NULL) {
        return;
    }

    node->next = free_list;
    free_list = node;
}
How the Memory Pool Works
A fixed array reserves memory for a predefined number of nodes.
Initialization links all unused nodes into a free list.
Allocation removes one node from the free list.
The application uses the node in its active linked list.
Release returns the node to the free list for reuse.
Embedded Systems Application
A memory pool is useful in sensor gateways, communication modules, and event-driven firmware where the maximum number of active nodes can be estimated.
Advantages:
Predictable memory consumption.
No per-node heap allocation.
Constant-time allocation and release in this basic implementation.
Reduced risk of heap fragmentation caused by node allocation and deallocation.
Important consideration: The pool must contain enough nodes for the maximum expected workload. This example is intended for single-threaded use; shared access from interrupts or multiple tasks requires appropriate synchronization.
Linked List Techniques: Time and Space Complexity
Understanding the performance of linked list operations helps developers select the right data structure for embedded applications. Microcontrollers often operate with limited RAM and processing power, so the cost of each operation matters.
The following table summarizes the time complexity of the 10 techniques discussed above.
| Linked List Technique | Time Complexity | Auxiliary Space | Common Application |
|---|
| Traversal | O(n) | O(1) | Processing sensor readings |
| Insertion at the beginning | O(1) | O(1) | Adding new events |
| Insertion at the end | O(n)* | O(1) | Storing incoming data |
| Deletion by value | O(n) | O(1) | Removing completed events |
| Searching | O(n) | O(1) | Finding device records |
| Reversal | O(n) | O(1) | Reordering data |
| Finding the middle node | O(n) | O(1) | Dividing a list |
| Cycle detection | O(n) | O(1) | Debugging pointer errors |
| Circular list traversal | O(n) per complete cycle | O(1) | Repeated task processing |
| Fixed-size memory pool allocation | O(1) | O(1) per operation | Predictable node allocation |
*n represents the number of nodes. Insertion at the end takes O(n) when only the head pointer is available. Maintaining a tail pointer reduces the insertion operation to O(1). The fixed-size memory pool example also uses O(NODE_POOL_SIZE) storage for the pool itself, even though each allocation or release requires O(1) auxiliary space.
These complexities describe algorithmic performance. Actual execution time on a microcontroller also depends on processor architecture, compiler optimization, memory placement, and the application.
Best Practices for Using Linked Lists in Embedded Systems
Linked lists provide flexibility, but incorrect pointer handling can introduce memory corruption, crashes, and difficult-to-diagnose firmware defects.
Follow these practices when implementing linked lists in C or C++ firmware.
1. Choose the Right Memory Allocation Strategy
Avoid assuming that dynamic allocation is always appropriate for embedded applications.
Consider these options:
Static allocation: Reserve memory at compile time when the maximum storage requirement is known.
Fixed-size memory pools: Reuse predefined nodes without allocating from the general-purpose heap.
Dynamic allocation: Use malloc() and free() when variable-sized allocation is justified and the memory requirements are understood.
For safety-critical or real-time systems, predictable allocation and execution behavior may be essential.
2. Check Pointers Before Accessing Nodes
Before accessing a node’s members, ensure the pointer is valid and the node remains allocated.
For example:
if (current != NULL) {
    /* Access current->data safely,
       assuming current points to a valid live node. */
}
A null check does not protect against every pointer error. A dangling pointer or corrupted non-null address can still cause undefined behavior.
3. Avoid Memory Leaks
Every dynamically allocated node should have a clearly defined ownership and release strategy.
Common causes of memory leaks include:
Removing a node without releasing its allocated memory.
Losing the pointer to a dynamically allocated node.
Repeatedly allocating nodes without limiting the list’s growth.
Failing to clean up a list when a module is shut down.
4. Keep Interrupt Service Routines Short
Avoid performing lengthy linked list operations inside an interrupt service routine.
For example, traversing a long list to insert a sensor event may increase interrupt latency.
A better approach in many applications is to capture the event quickly and defer processing to the main loop, an RTOS task, or another suitable execution context.
The exact design depends on the processor, interrupt priorities, and synchronization requirements.
5. Consider Memory Overhead
Every node requires memory for its data and pointers. On a small microcontroller, pointer storage can represent a significant portion of the total node size.
Consider this example:
typedef struct Node {
    uint16_t sensor_value;
    struct Node *next;
} Node;
The structure contains a 16-bit sensor value and a pointer. Its actual size depends on the target architecture, compiler, alignment, and padding.
Use sizeof(Node) on the target platform to determine the actual structure size.
6. Test Boundary Conditions
A linked list should be tested with more than just a typical sequence of nodes.
Important test cases include:
An empty list.
A list containing one node.
Insertion at the beginning and end.
Deletion of the first and last nodes.
Searching for a value that does not exist.
Reversing an empty or single-node list.
Allocation failure.
Repeated insertion and deletion.
Invalid pointers and unintended cycles.
Testing these cases helps identify problems before the code is deployed in firmware.
Linked List vs. Array vs. Ring Buffer in Embedded Systems
Linked lists are not the only option for storing data in embedded applications. Arrays and ring buffers are often more suitable when memory and execution time must be predictable.
| Feature | Linked List | Array | Ring Buffer |
|---|
| Memory layout | Nodes may be scattered in memory | Contiguous | Contiguous |
| Size | Can grow or shrink, depending on allocation | Usually fixed | Fixed capacity |
| Direct indexing | Not supported | Supported | Supported through index calculations |
| Insert at beginning | O(1) with a head pointer | O(n) when shifting elements | Depends on the operation and design |
| Append operation | O(1) with a tail pointer; otherwise O(n) | O(1) when capacity and current length permit | Typically O(1) |
| Memory overhead | Additional pointer storage | No per-element pointer required | Small amount of index and state storage |
| Allocation predictability | Depends on allocation strategy | High with static allocation | High with static allocation |
| Typical use | Dynamic collections and resource tracking | Fixed datasets and lookup tables | Sensor streams and communication queues |
Which Data Structure Should You Choose?
Choose a linked list when:
The number of elements changes during execution.
Frequent insertion and deletion are required.
Nodes must be linked without shifting an array’s elements.
The application can safely manage pointer and memory overhead.
Choose an array when:
The number of elements is known.
Fast indexed access is important.
Contiguous memory is beneficial.
The implementation needs a simple and predictable storage layout.
Choose a ring buffer when:
Sensor readings arrive continuously.
Data is processed in FIFO order.
A fixed amount of memory must be reused.
Predictable insertion and removal times are important.
For many microcontroller applications, a statically allocated ring buffer is a strong choice for continuous sensor sampling and UART, SPI, or other communication data streams. A linked list becomes more attractive when the application needs flexible node relationships or frequent structural changes.
Conclusion
Linked list techniques provide embedded developers with a flexible way to organize data and manage nodes through pointers. Understanding traversal, insertion, deletion, searching, reversal, cycle detection, circular linking, and memory pool management makes it easier to build and maintain reliable firmware.
However, flexibility should not come at the cost of predictable performance. Microcontrollers often operate with limited RAM and strict timing constraints, so the choice of data structure should match the application’s actual requirements.
The key principle is simple: use linked lists when their dynamic structure provides a clear advantage, and consider arrays, ring buffers, or fixed-size memory pools when predictable memory use and execution time are more important.
By selecting the right technique and implementing it carefully in C or C++, developers can build more efficient data-handling components for embedded systems, microcontrollers, and IoT applications.