What Is Shared Memory in Linux?
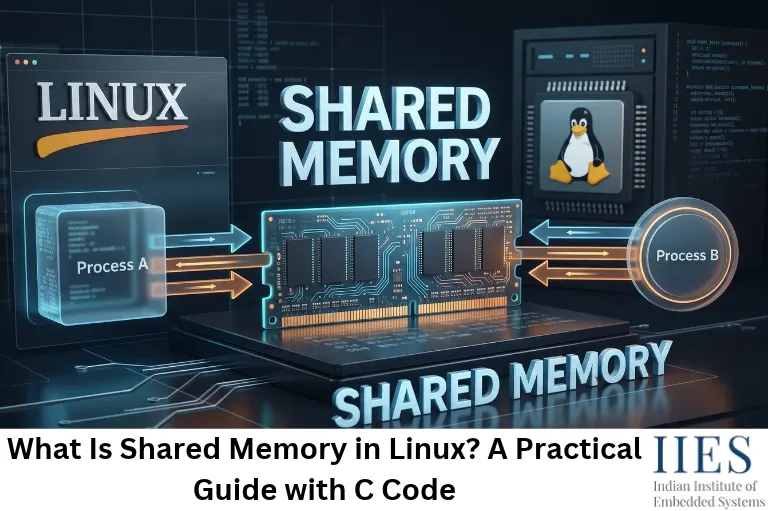
Shared memory in Linux is a region of RAM that multiple processes map into their address spaces at the same time. Once the mapping exists, each process reads and writes it with ordinary pointer operations. No read() or write() system call and no kernel buffer sits in between.
Here is an everyday way to picture it:
- Pipes, sockets and message queues work like emailing a spreadsheet back and forth. Every update creates a new copy, and the operating system plays the mail server.
- Shared memory works like two engineers editing one live spreadsheet. Both see every change instantly, and nothing is copied.
- The catch is the same one you have seen in live documents: if both people type in the same cell at the same moment, one edit overwrites the other. In code, that is a race condition, and it is why synchronization matters.
Key characteristics
- Same physical pages, different virtual addresses: each process may see the region at a different address.
- The kernel only sets things up: it creates the object, maps it and cleans it up. After that, your code talks to memory directly.
- Page-granular: sizes are rounded up to the page size, usually 4 KB (check with getconf PAGE_SIZE).
- No built-in protection: the kernel will not stop two processes from writing at the same time.
- Same machine only: shared memory cannot span a network.
How Shared Memory Works Under the Hood
- Every Linux process gets its own virtual address space. The MMU uses page tables to translate virtual addresses into physical ones.
- Normally, two processes have page tables that point to different physical page frames, so they cannot see each other’s data.
- Shared memory changes one thing: page-table entries in both processes point to the same physical frames.
- These pages are backed by the kernel’s shmem (tmpfs) layer. They behave like RAM-backed files and can be swapped out unless you lock them with mlock().
- After mapping, access is a plain load or store instruction. The first touch of a page may cause a page fault that the kernel resolves, but the steady-state data path does not involve the kernel.
Process A (virtual)                          Process B (virtual)

 +-------------------+                        +-------------------+

 | stack             |                        | stack             |

 | shared region ----+-----> [ same ] <-------+---- shared region |

 | heap              |      [ physical ]      | heap              |

 | code              |      [  page(s) ]      | code              |

 +-------------------+                        +-------------------+
- Quick check: open /proc//maps for a process using shared memory. Shared mappings show an s in the permissions column (for example rw-s), while private mappings show p.
Why Is Shared Memory the Fastest IPC Mechanism?
Shared memory is the fastest IPC mechanism because processes access the same physical memory directly. Pipes, sockets and message queues copy every message from the sender into a kernel buffer and then into the receiver, using a system call on each side. Shared memory removes those copies and system calls from the data path.
Pipe, socket or message queue:

  Sender buffer --copy 1--> Kernel buffer --copy 2--> Receiver buffer

         (write() syscall)                (read() syscall)

Shared memory:

  Sender --store--> [ shared page ] <--load-- Receiver

         (no kernel copy, no syscall per message)
The four reasons it wins
- No kernel copies. A pipe write copies data from user space into the kernel, and the read copies it back out. That is two copies per message. With shared memory, the producer writes once and the consumer reads in place.
- No system call per message. Every read() and write() crosses the user/kernel boundary, which costs mode switches and disturbs CPU caches. The shared memory data path needs none of that. With atomics or futex-based locks, you enter the kernel only when a process must sleep or be woken.
- The kernel leaves the data path. It is involved at setup and teardown, not on every message.
- The gap grows with payload size. Sending a 4 MB camera frame through a pipe means copying 4 MB twice and feeding it through a pipe buffer that defaults to 64 KB. With shared memory, you write the frame once and pass a small index or offset.
The fine print (honest engineering)
- Synchronization has a cost. For tiny messages, lock handling and wake-ups can outweigh the copy savings.
- Cache coherence still applies. When one core writes and another reads, cache lines move between cores. Avoid false sharing by aligning hot fields to cache-line boundaries (commonly 64 bytes).
- First-touch page faults. Touch or pre-fault pages at startup (for example with MAP_POPULATE) if you need predictable latency.
- Simplicity matters. For low-rate control messages, a pipe or UNIX domain socket is easier and usually fast enough.
Verify it yourself
- Write a pipe-based producer and consumer, and a shared memory version that passes the same data.
- Run each under strace -c -f ./your_program.
- Compare the syscall counts: the pipe version shows a read and write per message, while the shared memory version shows almost none in the steady state.
Types of Shared Memory in Linux
- POSIX shared memory (shm_open() + mmap()): file-descriptor based, with objects living in /dev/shm. Clean API and the best choice for new code.
- System V shared memory (shmget(), shmat(), shmdt(), shmctl()): the older, key-based API (keys usually come from ftok()). Common in legacy code and databases.
- Anonymous shared mapping (mmap() with MAP_SHARED | MAP_ANONYMOUS): shared between a parent and its children after fork(). No names, no cleanup.
- File-backed shared mapping (mmap() on a regular file with MAP_SHARED): processes share the file’s pages, and changes are written back to disk (use msync() to force it).
- memfd_create() (Linux 3.17 and later): creates an anonymous memory-backed file descriptor you can hand to another process over a UNIX domain socket. Supports sealing for safer sharing.
Which one should you pick?
- Unrelated processes that find each other by name: POSIX shared memory
- Parent and child processes: anonymous MAP_SHARED
- Maintaining older code: System V
- Passing a handle to a sandboxed or untrusted process: memfd_create()
POSIX Shared Memory Example in C
Let’s build the smallest useful example: one process writes a message, another reads it.
writer.c
#include

#include

#include

#include <sys/mman.h>

#include <sys/stat.h>

#include

#define SHM_NAME "/iies_demo"

#define SHM_SIZE 4096

int main(void) {

    int fd = shm_open(SHM_NAME, O_CREAT | O_RDWR, 0600);

    if (fd == -1) { perror("shm_open"); return 1; }

    if (ftruncate(fd, SHM_SIZE) == -1) { perror("ftruncate"); return 1; }

    char *ptr = mmap(NULL, SHM_SIZE, PROT_READ | PROT_WRITE, MAP_SHARED, fd, 0);

    if (ptr == MAP_FAILED) { perror("mmap"); return 1; }

    strcpy(ptr, "Hello from the writer process!");

    puts("Writer: message placed in shared memory");

    munmap(ptr, SHM_SIZE);

    close(fd);

    return 0;

}
reader.c
#include

#include

#include <sys/mman.h>

#include <sys/stat.h>

#include

#define SHM_NAME "/iies_demo"

#define SHM_SIZE 4096

int main(void) {

    int fd = shm_open(SHM_NAME, O_RDONLY, 0);

    if (fd == -1) { perror("shm_open"); return 1; }

    char *ptr = mmap(NULL, SHM_SIZE, PROT_READ, MAP_SHARED, fd, 0);

    if (ptr == MAP_FAILED) { perror("mmap"); return 1; }

    puts(ptr);

    munmap(ptr, SHM_SIZE);

    close(fd);

    shm_unlink(SHM_NAME);   /* remove the name when finished */

    return 0;

}
Compile and run
gcc writer.c -o writer

gcc reader.c -o reader      # add -lrt on glibc older than 2.34

./writer

ls -l /dev/shm/iies_demo    # the object exists even though the writer exited

./reader
What just happened
- shm_open() created a named object in /dev/shm. Names must start with a slash and contain no other slashes.
- ftruncate() set its size, because a new object starts at zero bytes.
- mmap() with MAP_SHARED mapped it into the process. Without MAP_SHARED, writes would not be visible to other processes.
- The reader mapped the same object and saw the same bytes.
- shm_unlink() removed the name. The memory is freed once the last process unmaps it.
- Important: this demo skips synchronization because the writer finishes before the reader starts. Never depend on timing in real programs.
Synchronization: The Price of Speed
- Why it is needed: nothing stops two processes from touching the same bytes at the same time, so shared structures can be read half-updated.
- Process-shared mutexes: place a pthread_mutex_t inside the segment and initialize it with PTHREAD_PROCESS_SHARED.
- Robust mutexes: add PTHREAD_MUTEX_ROBUST so that if a process dies holding the lock, the next locker gets EOWNERDEAD and can repair the state instead of hanging forever.
- POSIX semaphores: use sem_open() for named ones, or sem_init() with pshared = 1 inside the shared region. Named semaphores also appear under /dev/shm.
- Atomics and lock-free queues: a single-producer, single-consumer ring buffer needs only head and tail indices and C11 acquire/release ordering.
- Memory ordering matters: compilers and CPUs reorder operations. A plain flag variable is not a safe signal between processes.
Useful Commands to Inspect Shared Memory
- ipcs -m: lists System V shared memory segments, with owner, size and number of attachments
- ipcs -lm: shows System V limits (shmmax, shmall, shmmni)
- ipcrm -m : removes a System V segment
- ls -l /dev/shm and df -h /dev/shm: show POSIX shared memory objects and the tmpfs size
- cat /proc//maps: reveals mappings, with rw-s for shared ones
- grep -i shmem /proc/meminfo: shows total shared memory in use (tmpfs, System V and shared anonymous pages)
- lsof /dev/shm/iies_demo: shows which processes have the object open or mapped
Shared Memory vs Other IPC Mechanisms
- Pipes and FIFOs: simple byte streams, kernel-buffered, two copies per transfer.
- Message queues: structured messages with priorities, kernel-buffered, with size limits.
- UNIX domain sockets: flexible and bidirectional, can pass file descriptors, but data is still copied through the kernel.
- Signals: tiny notifications only. They carry no real data.
- Shared memory: fastest for large or frequent data, but you design the protocol and the locking.
- Rule of thumb: keep bulk data in shared memory and use a semaphore, eventfd or socket only to signal that new data is ready.
Where Shared Memory Is Used in the Real World
- PostgreSQL: backend processes share one buffer cache and lock state through shared memory.
- Display servers: Wayland clients hand pixel buffers to the compositor through shared memory, and X11 offers the MIT-SHM extension for the same reason.
- Robotics and automotive: zero-copy middleware such as Eclipse iceoryx (used with ROS 2) passes camera frames and lidar point clouds by reference instead of copying them.
- Embedded Linux gateways: a common pattern is an acquisition process writing sensor samples into a ring buffer while logging and UI processes read from it.
Common Mistakes to Avoid
- Storing raw pointers inside the segment. Each process may map the region at a different address. Store offsets from the base address instead.
- Skipping synchronization because ‘it worked on my machine’. Races show up under load.
- Leaking segments. System V segments persist until removed or reboot. Always call shmctl(IPC_RMID) or shm_unlink().
- Ignoring size limits. /dev/shm defaults to half of RAM, and Docker containers get only 64 MB unless you set –shm-size.
- Trusting the data. Any process with access can write anything. Set permissions such as 0600 and validate what you read.
- Assuming layout compatibility. Different compilers, padding and versions can break shared structs. Version your header and use fixed-width types.
Key Takeaways
- Shared memory in Linux maps the same physical pages into multiple processes, so they exchange data without kernel copies.
- It is the fastest IPC mechanism for bulk data on one machine because it removes copies and per-message system calls.
- Use POSIX shared memory (shm_open + mmap) for new code.
- Synchronization is your responsibility: mutexes, semaphores or atomics.
- Clean up with shm_unlink() or ipcrm, and watch /dev/shm limits in containers.
Conclusion
So, what is shared memory in Linux? It is one set of physical pages that several processes map into their own address spaces, giving them a direct, copy-free channel to exchange data. That is exactly why shared memory is the fastest IPC mechanism on a single machine, and why it comes with the extra responsibility of synchronization and cleanup.
Ready to go deeper into Linux internals and embedded systems on real hardware? Explore what IIES offers in embedded systems and build these skills hands-on.